

M2P Fintech
Fintech is evolving every day. That's why you need our newsletter! Get the latest fintech news, views, insights, directly to your inbox every fortnight for FREE!

Picture this.
It's a cozy Saturday night, and you decide to treat your family to a delightful dinner at a renowned fine-dining restaurant. However, you arrive to find the place fully booked, with no available tables. Undeterred, you jot down your name and phone number on their waitlist.
The receptionist, in this case, becomes the intermediary, assuring you that they'll give you a call as soon as a table becomes available.
In the digital realm, webhooks operate in a similar fashion. One system subscribes to monitoring specific events, just like you put your name on the waitlist. When that event occurs, Computer B (akin to the receptionist) sends a notification to Computer A (you) about the event's occurrence. Webhooks act as the messengers of the tech world, facilitating seamless communication between applications whenever an event takes place.
So, what exactly are webhooks? Why are they important? And how can you master webhook design?
Keep reading, as our Software Expert, Pratik Jain, takes you deep into the world of webhooks. Please note that this blog is not a hands-on tutorial. It discusses the technical design/solution aspects involved in creating a webhooks framework with exponential delay in retries.
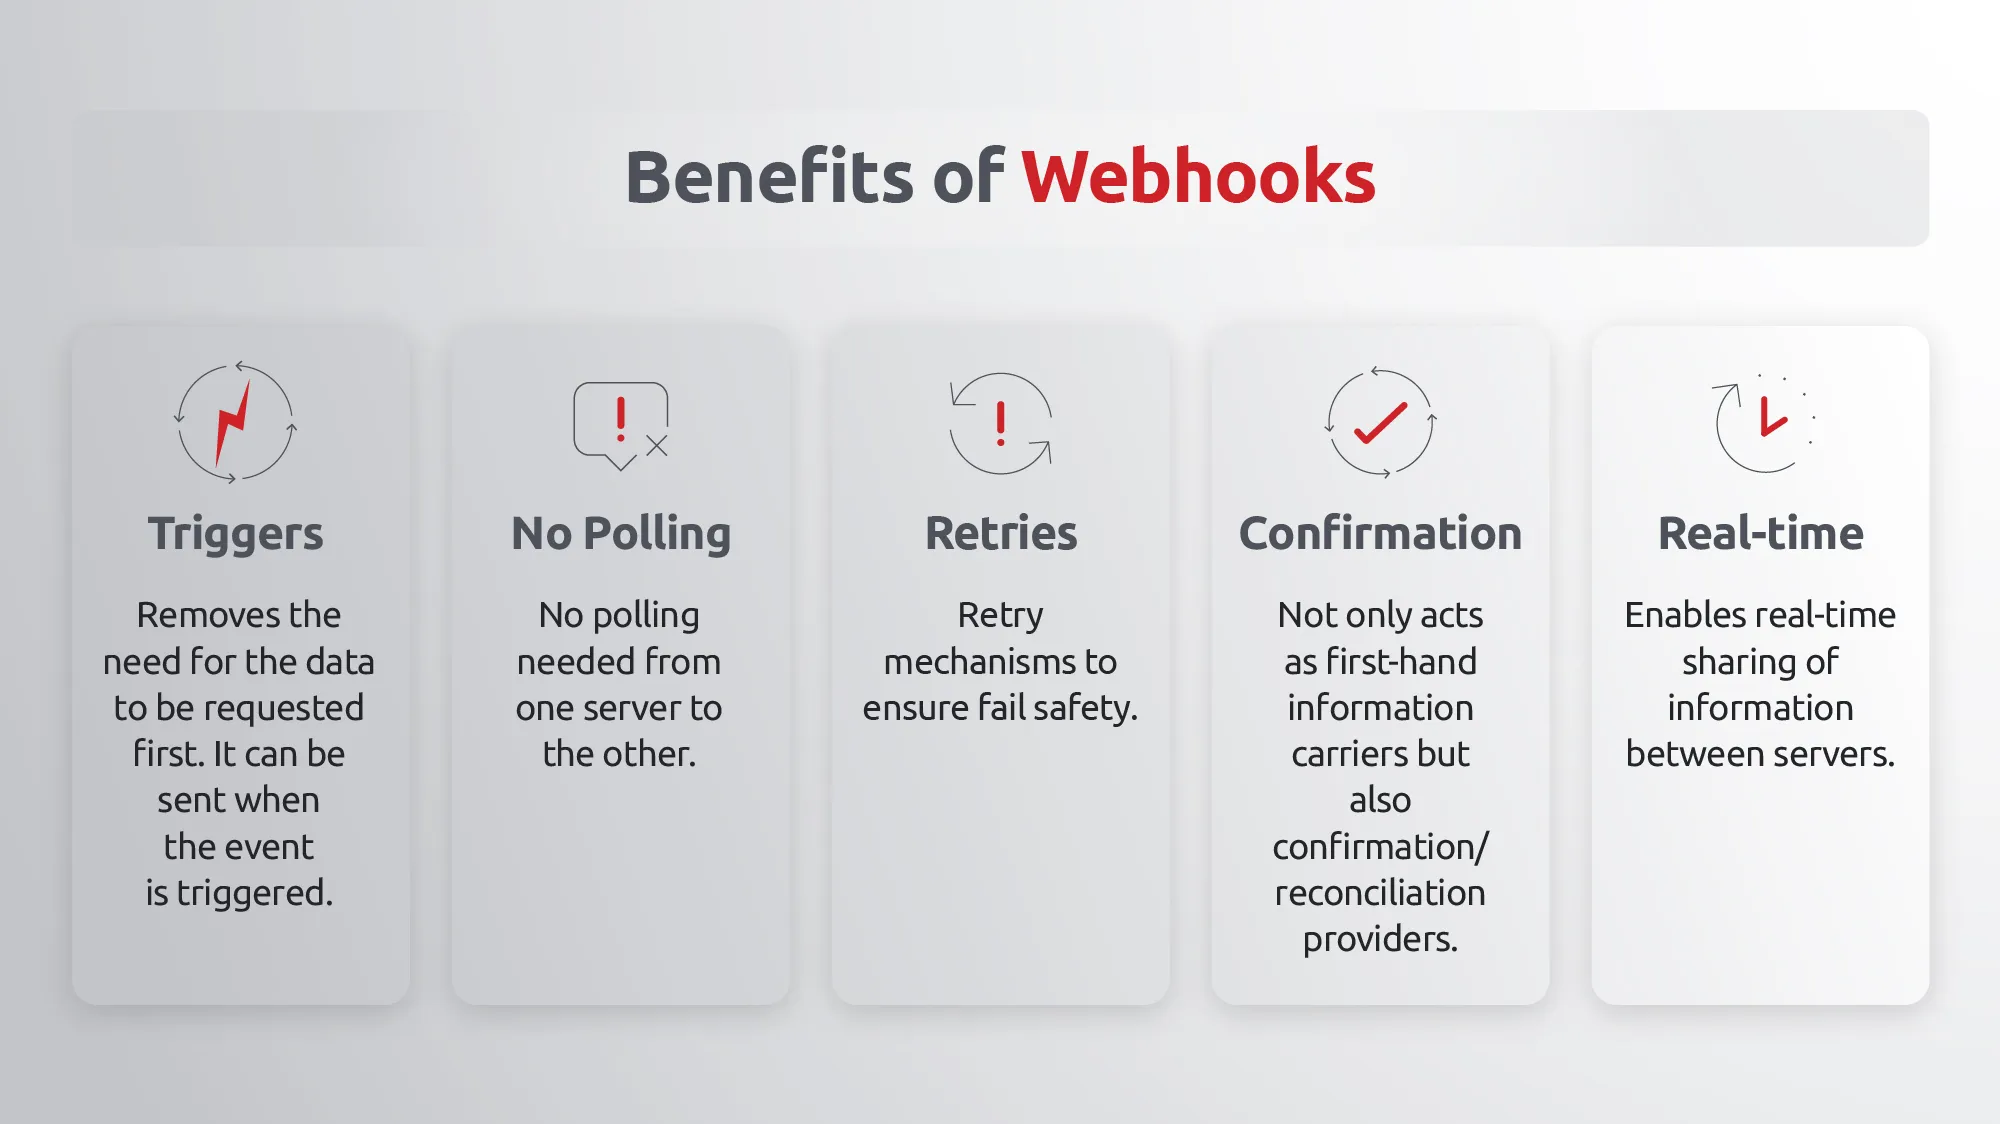
Simply put, webhooks are an alternate form of notification service. To get a better idea, let’s recall the previous scenario, but without a waitlist notepad. In this case, you find yourself having to visit the reception every few minutes just to inquire about table availability. This becomes a tedious and time-consuming task for both you and the restaurant staff.
The constant need to ask for updates at regular intervals, like every second or minute, is akin to what is known as polling in computer science. In this context, polling is highly in and resource-intensive for both parties involved.
Webhooks eliminate the need for one server to continuously check (or "poll") another server for updates. Polling is not optimal and consumes lots of resources on both ends. Instead, a webhook only triggers when a specific event, like your table being ready, occurs. This event then promptly initiates the communication from one server to the other in a swift, efficient, and real-time manner.
Now, imagine the receptionist calls to inform you, but you miss the call. She doesn't give up; she tries again. Even if you still don't pick up, she persists with one last attempt. Finally, when you do answer, you receive the information you've been waiting for.
In a similar fashion, when one server sends a request to another server, there's a chance that the first request might time out or the receiving server could be temporarily unavailable. This can result in no response being received. However, webhooks come with built-in retry mechanisms that ensure fail-safety, a feature that normal API requests typically lack.
Let’s break our webhooks exploration into three sections.
Let us try to create webhooks for merchants to receive notifications when an order is successfully paid or failed. The system would notify their servers whenever a payment is made on the platform.
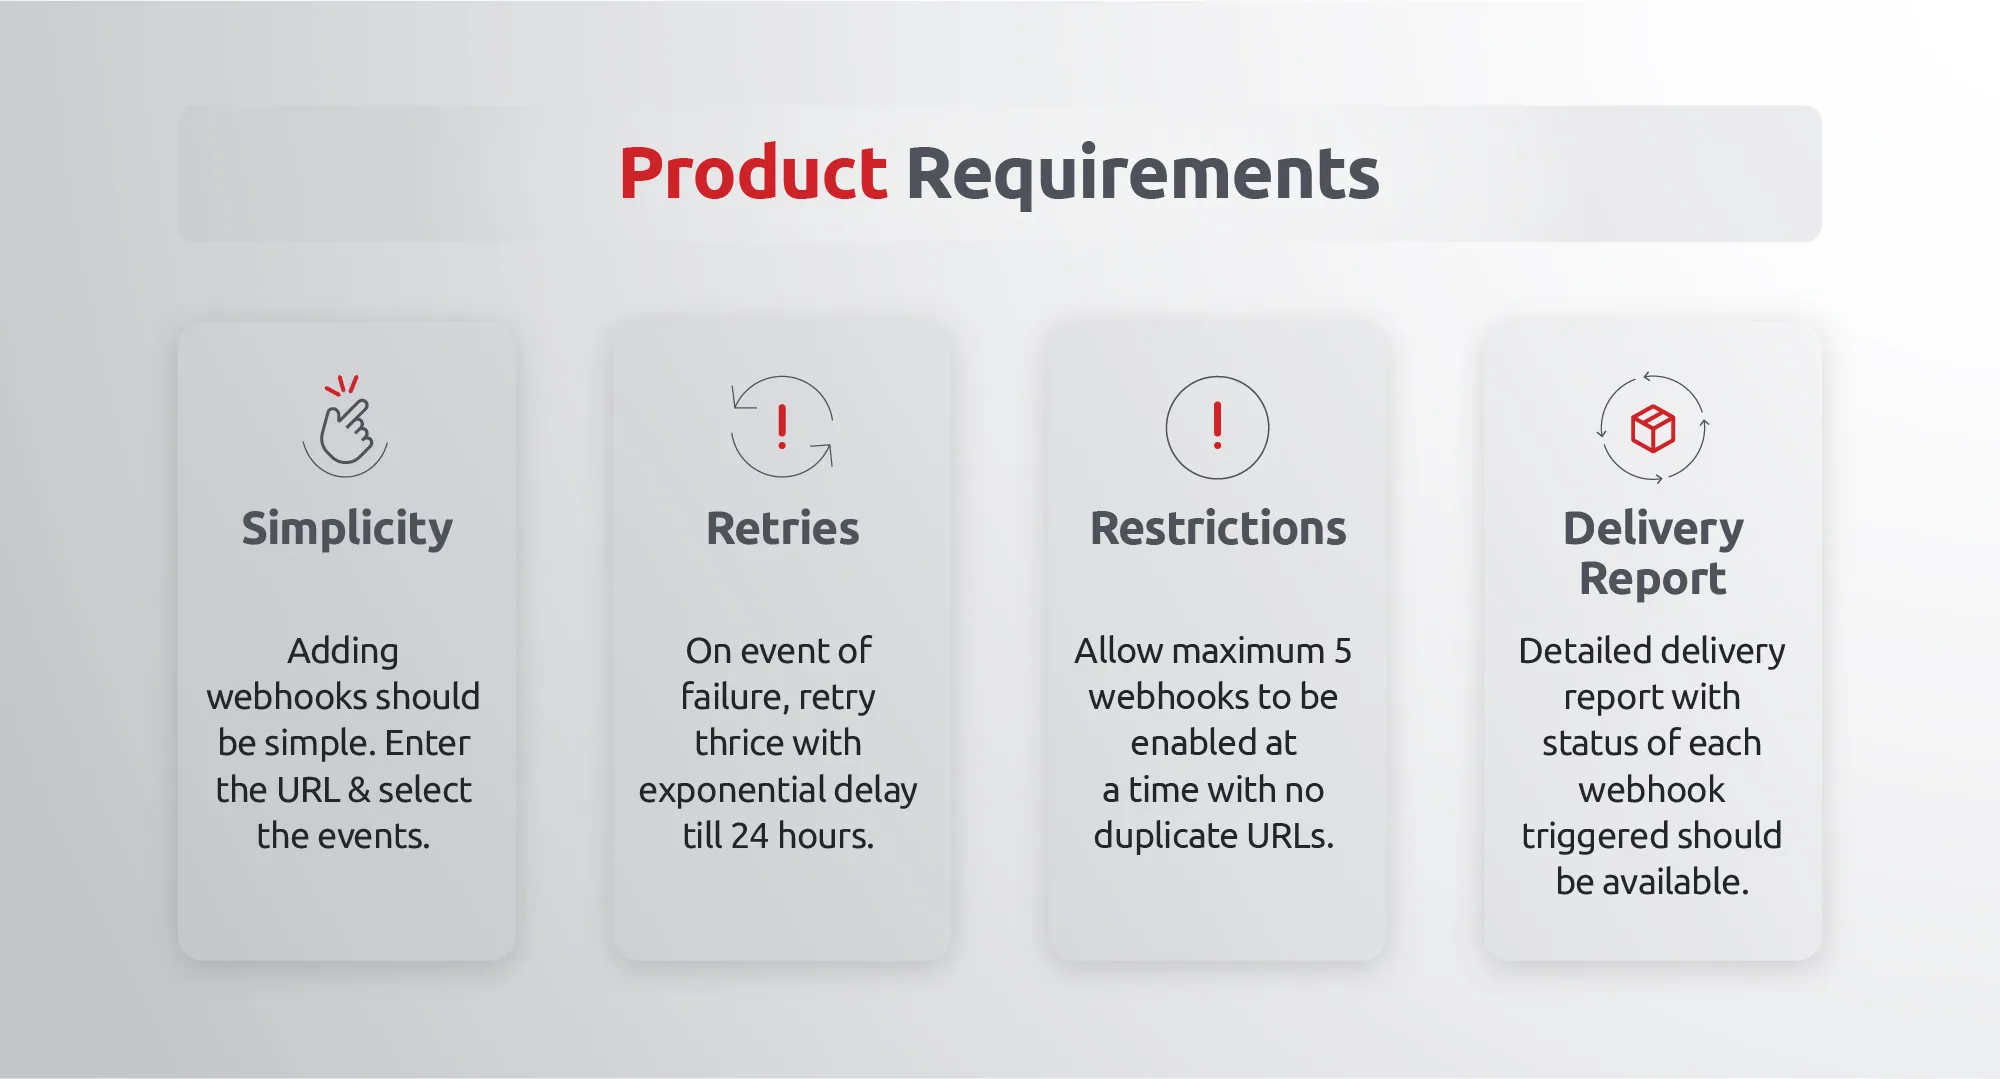
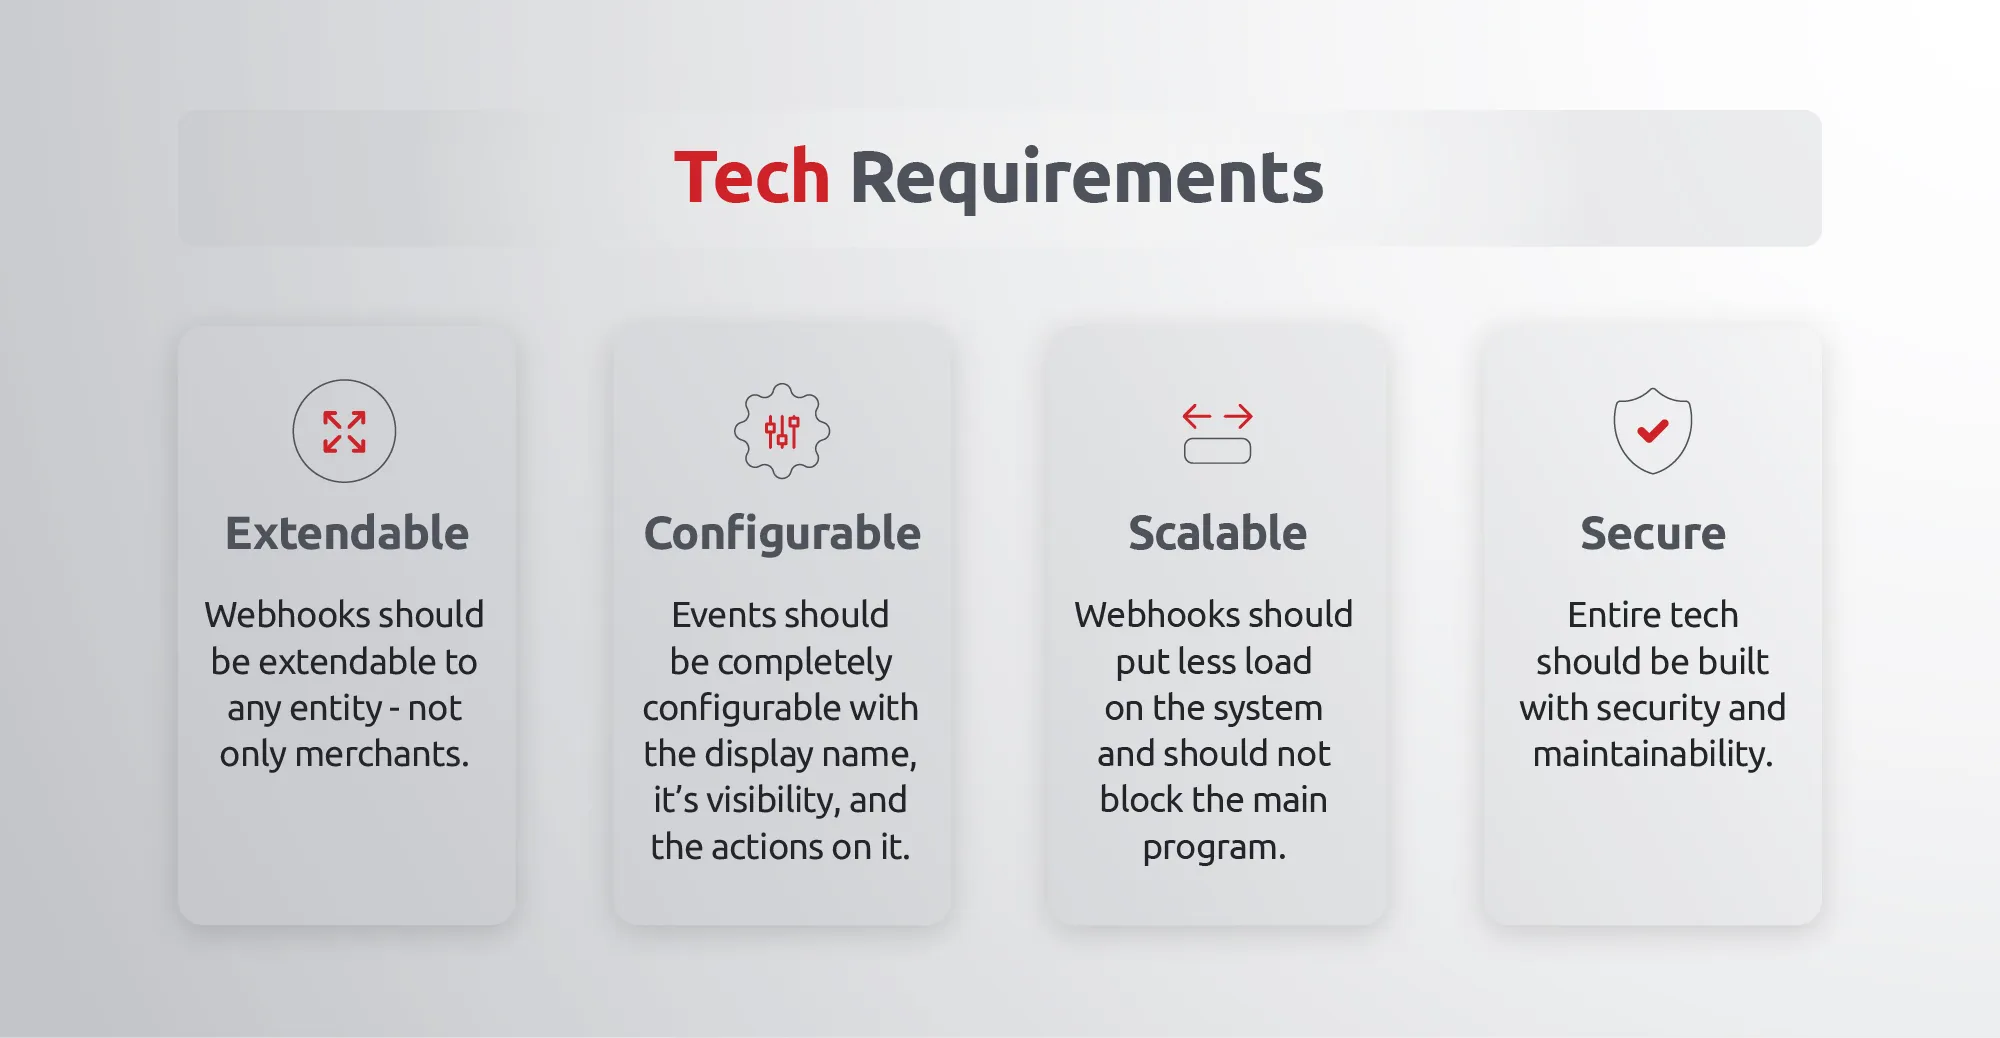
The webhooks framework enables real-time communication and event-driven interactions between different systems or services, allowing them to stay synchronized and respond promptly to relevant events.
Adding a webhook is simple. Below is the sample visual snapshot from the dashboard.
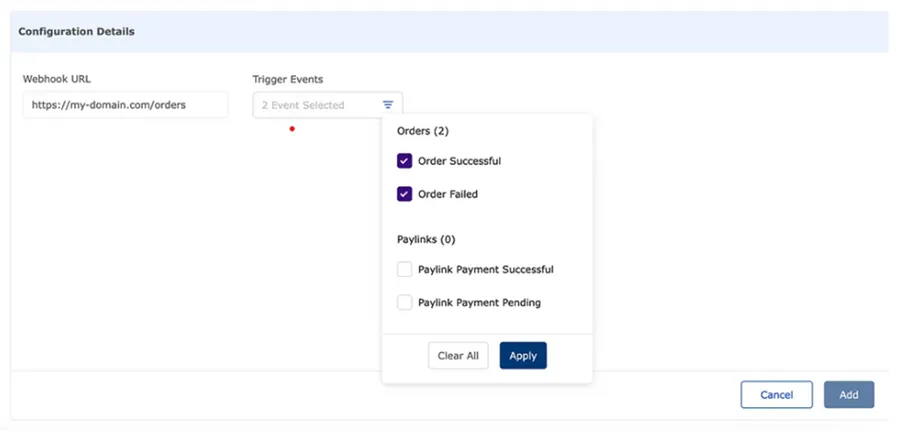
Input the Webhook URL and choose the events you wish to listen or subscribe to. That’s all the configuration you need. Whenever one of these events takes place, we'll send a notification to the provided Webhook URL, which is the merchant's server URL. For example, if Amazon is a merchant, they will enter their webhook endpoint (they created) to receive the notifications for these events.
Let’s say a transaction is successful and the order is marked as a success. This will trigger the “Order Successful” webhook.
This webhook is published to a queue. The consumer service does the heavy lifting of figuring out which merchant needs to send the notification and then hits the merchant’s webhook URL.
If the merchant’s server responds to a webhook hit with an error, a message is published into another queue called “retry queue” which retries the above process. This retry mechanism continues till 3 retries are exhausted after which the webhook request’s status is marked as “failed” in the database.
Notably, the retry strategy incorporates an intelligent waiting period, following an exponential pattern. The intervals are strategically set at 5 minutes, followed by 2 hours, and then 10 hours. This deliberate design ensures ample time for the receiving server to potentially recover from any adverse or error-prone conditions before formally marking the webhook request as failed.
The detailed system architecture for this entire framework is broken down into 3 parts.
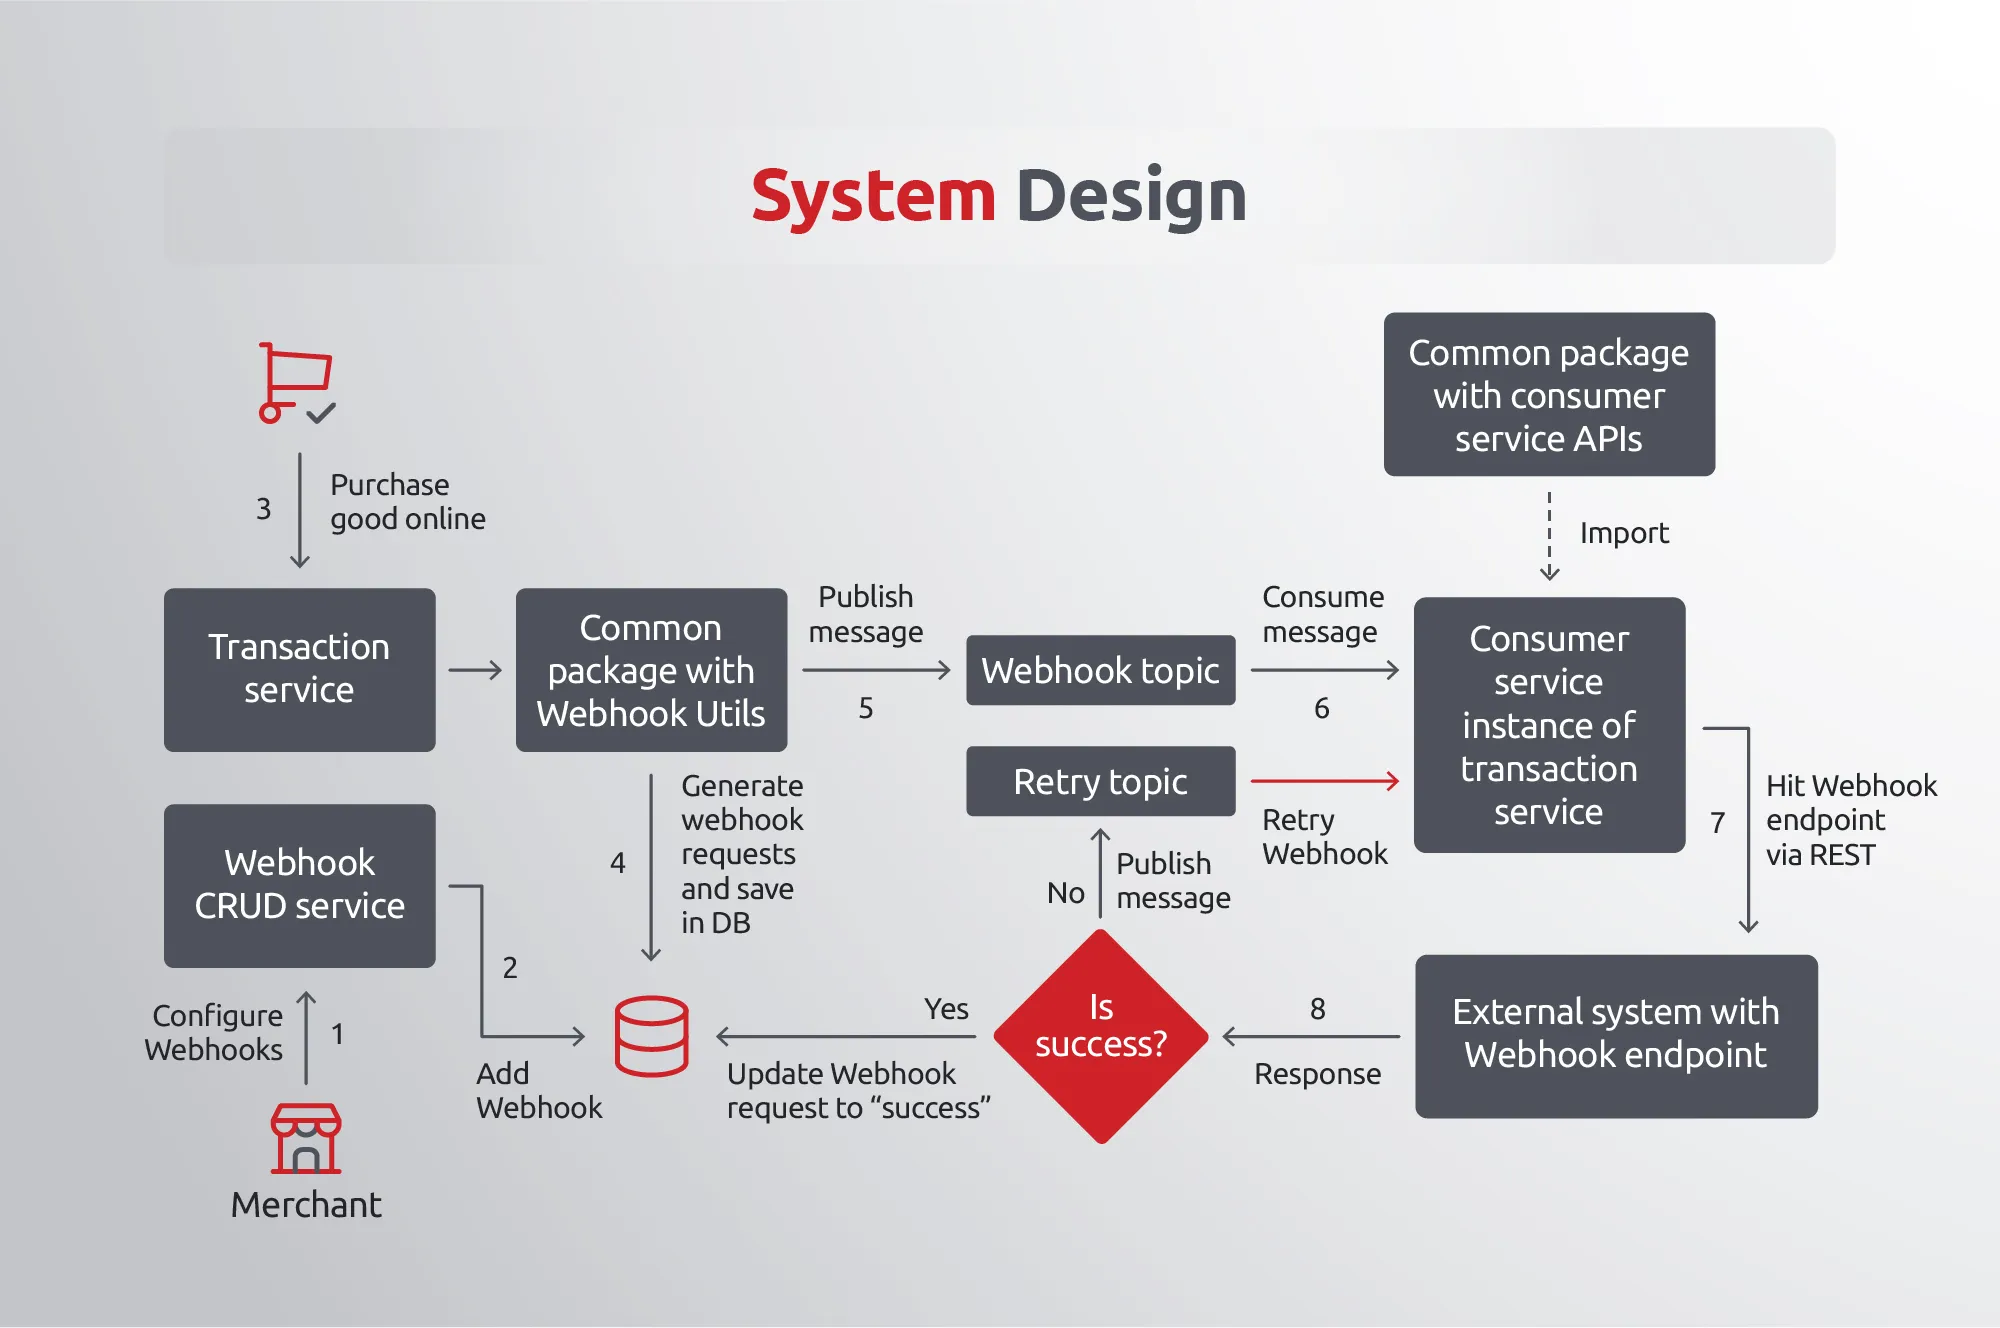
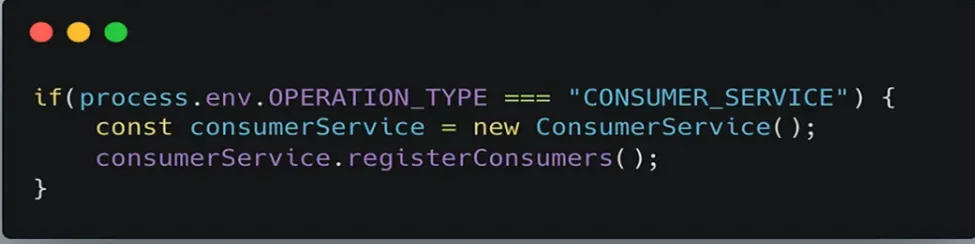
Important Note: The Transaction Service can be replaced with any other service because no logic related to Kafka / Webhooks is present inside it directly making it loosely coupled. They reside in commons library.
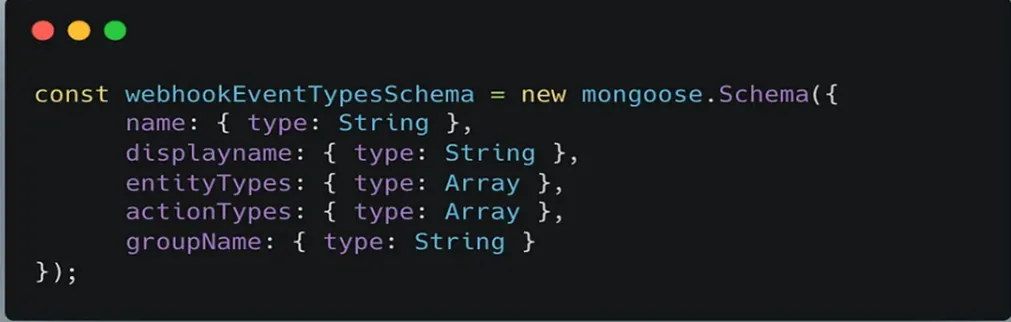
Designing the database is often the simplest aspect. The thumb rule of good software design is that whatever components change, we abstract it out of the main logic.
Now, let's consider what elements could potentially undergo changes.
Below is the code for a sample webhook event type Mongoose schema.
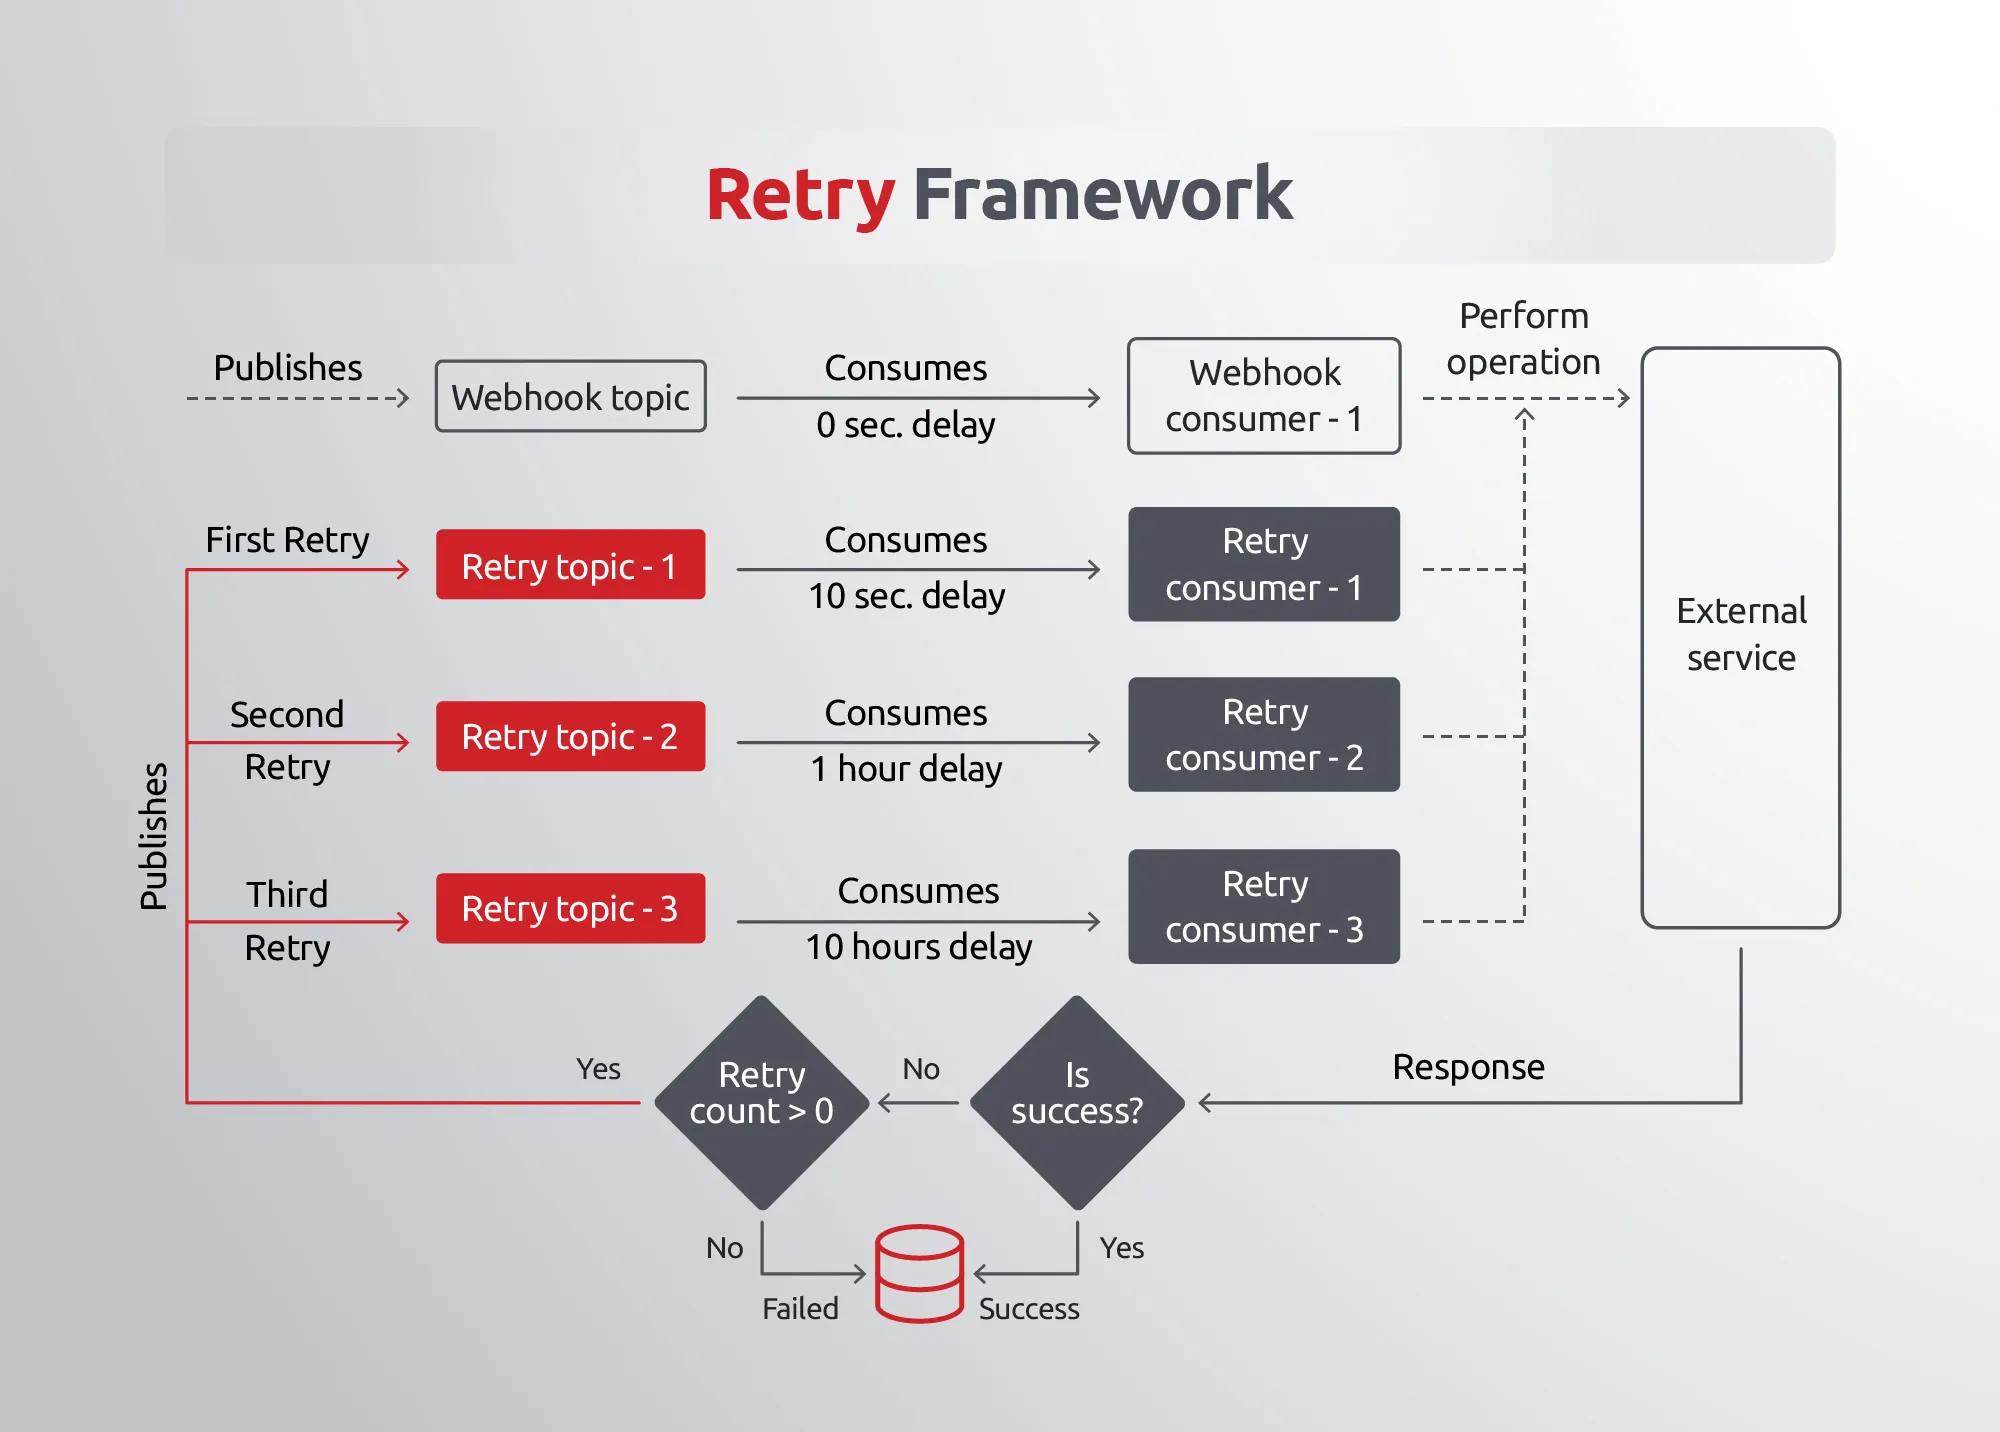
Kafka is used to ensure that the webhooks are not fired and forgotten. A retry framework is built which can be reused for any future use cases like notifications, auditing, etc.
Given below is a simple design of how the Kafka pipeline is implemented in the application.
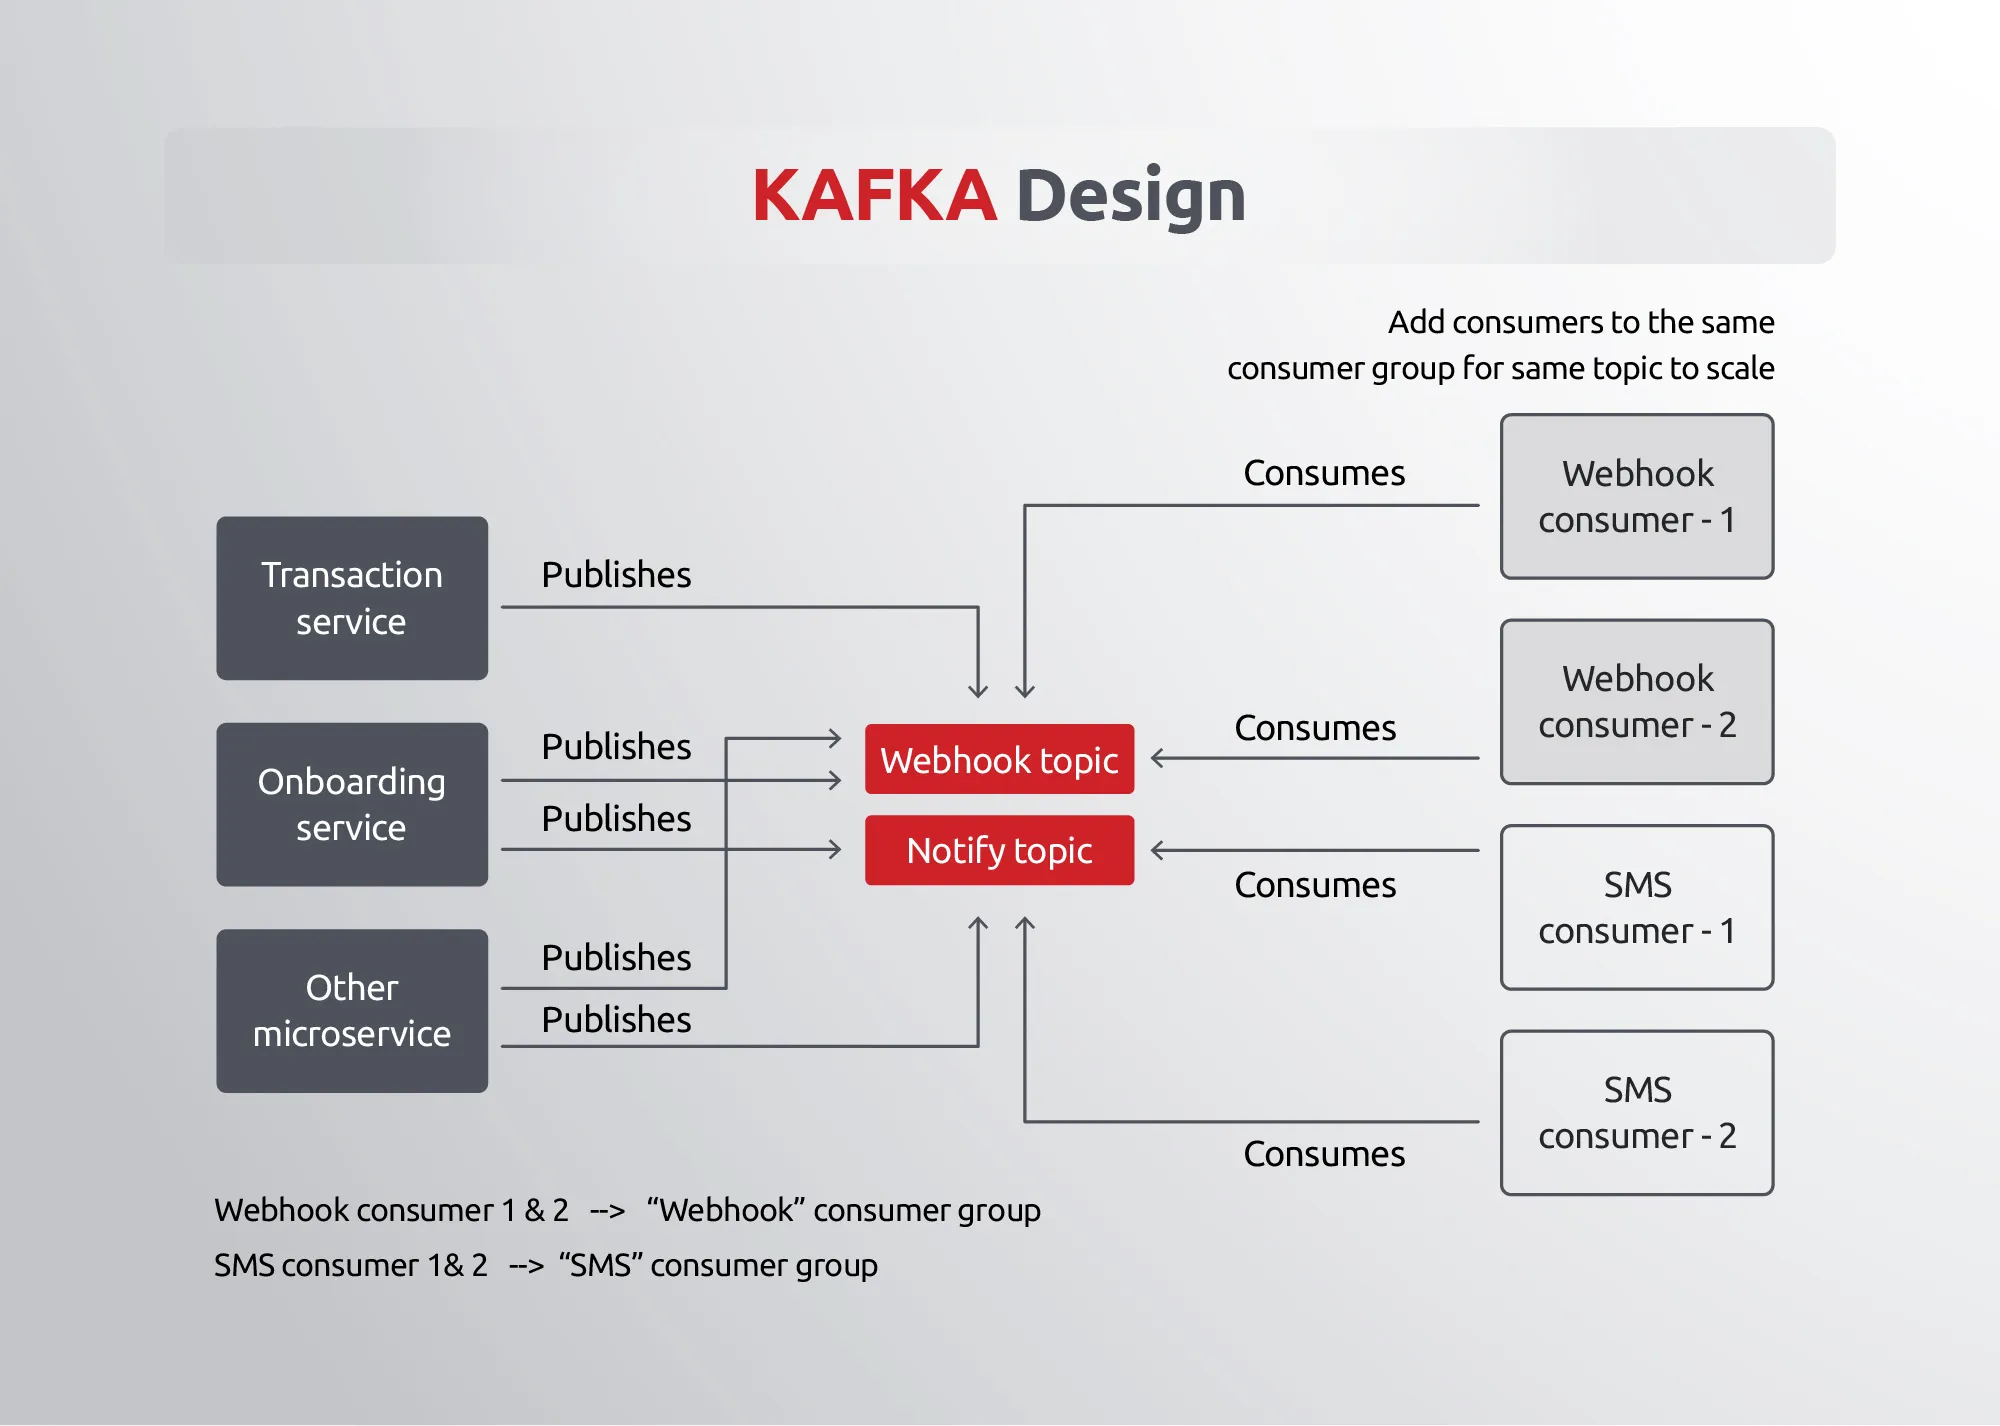
To expand upon this framework, there is a flexibility to introduce various consumer groups in Kafka, each capable of executing distinct actions beyond simply triggering webhooks. Furthermore, there are options to continuously integrate additional microservices that contribute to the same topic.
Since Kafka's partition distribution among consumer groups aids in scalability, the focus is on the retry framework.
When translated to code, the configuration looks something like this.
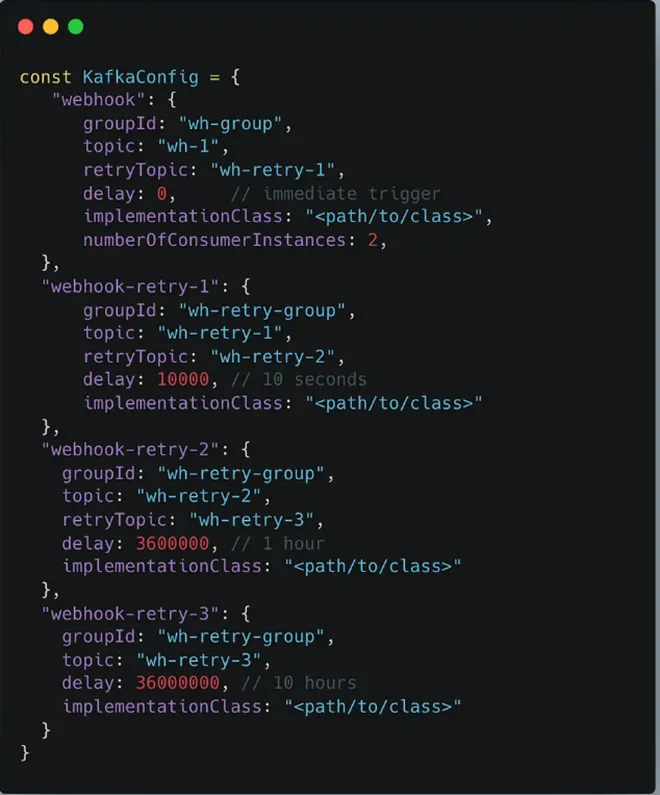
The way to achieve and build a retry framework is to harness the power of pausing and resuming the consumer. By leveraging different consumers for different retry topics, you can pause and resume separate consumers depending on the delay you want the topic to create.
The kafka.js library uses eachMessage() API to poll the topic and consume messages, but it sends the heartbeat to the broker after it has read each message. So, if consuming a message takes more than “session timeout” then the broker will think the consumer is dead and rebalance the partitions assigned to that consumer. The ‘session timeout’ is increased to a bigger number, but then unhealthy consumers will be noticed very late which is not what they want.
Therefore, to solve this problem the application uses heartbeat () while consuming the messages from the topics. The eachMessage () API gives access to the heartbeat () function where the broker uses setInterval () every X seconds so that the consumer is alive which prevents unnecessary rebalancing of partitions.
With this, we have covered Webhook requirements in both product and tech. It is important to remember that mastering the art of webhooks design isn't just about code – it's about architecting connections that empower seamless communication in the digital world.
Want to know more about webhooks?
Get in touch with our experts today.
Subscribe to our newsletter and get the latest fintech news, views, and insights, directly to your inbox.
Follow us on LinkedIn and X for insightful fintech bytes curated for curious minds like you.


Fintech is evolving every day. That's why you need our newsletter! Get the latest fintech news, views, insights, directly to your inbox every fortnight for FREE!